Summary
As open and closed models get more capable, the gap between benchmark scores and real-world performance has become one of the hardest problems for model providers and their customers. Fixed benchmarks saturate quickly, their test questions often leak into training data, and they miss the nuances of specific domains. Arena fills that gap with a human preference platform where real, unpaid users compare anonymous model outputs across text, coding, vision, image generation, and agentic tasks. For agents specifically, Arena’s Agent Arena uses a causal inference methodology that observes the full human-agent workflow, not just the final output, to measure how well agents actually perform real work. Those first-party signals feed the public leaderboards labs and builders rely on. Salesforce Ventures is proud to participate in Arena’s Series B.
- Founders: Anastasios Angelopoulos, Wei-Lin Chiang, and Ion Stoica
- Sector: AI Infrastructure
- Location: San Francisco, CA
The Opportunity
Two years ago, picking a frontier model meant choosing between a handful of options. Today, a product team has dozens of closed and open-weight models to choose from, and the best option for a coding assistant, a support agent, or an image pipeline is constantly in flux depending on the latest model launches. Labs face the same problem in reverse. The cadence at which they ship new model versions has accelerated and they need to know whether the latest one is better for the people who will actually use it.
Fixed, static benchmarks only answer part of that question. They measure well-specified task completion but say little about vague instructions or multi-turn behavior such as how well a model recovers when a user pushes back, or finishes a 40-step task without inventing the result. That data comes from watching real people use models on their own problems, and almost nobody outside the labs has been able to collect it at scale.
The Solution
Arena‘s answer is a repository of real usage data. People come to Arena to use a wide range of current models, frontier and open-weight. Each prompt gets two anonymous responses, and the person votes for the one they prefer. For agents, Arena tracks each turn between user and agent and observes both explicit and implicit sentiment signals in the conversation to gauge how well the model is completing the task. Across text, coding and web development, vision, image and video generation, search, and multi-turn agent tasks, these votes and signals feed public leaderboards that labs and builders use to decide which models to train, ship, and buy. Arena also packages the data insights into detailed evaluation reports for labs and enterprises.
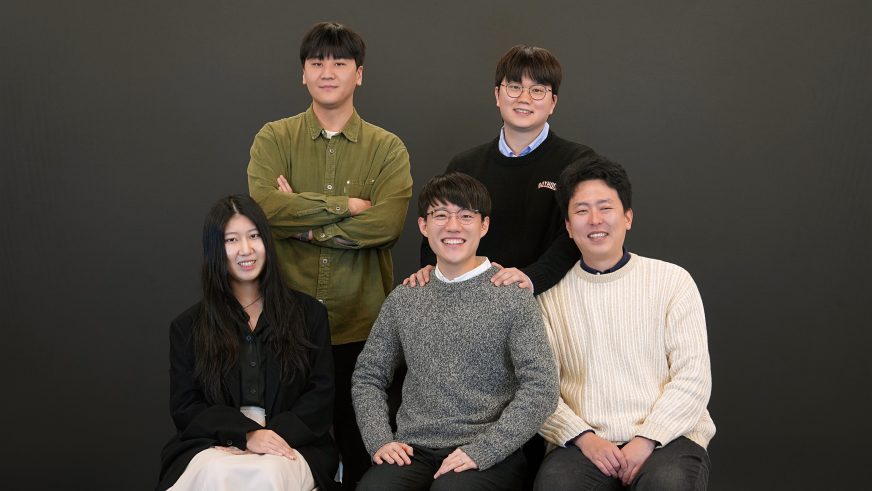
Arena started at UC Berkeley in 2023 as Chatbot Arena, a project of the Large Model Systems Organization (LMSYS) and Ion Stoica’s Sky Computing Lab. Ion’s earlier Berkeley labs produced Spark and Ray, which led to Databricks and Anyscale. Wei-Lin Chiang co-created Vicuna, one of the first widely used open chat models, and co-led Chatbot Arena from launch. Anastasios Angelopoulos, whose PhD focused on statistical methods for evaluating black-box models, co-wrote the Chatbot Arena paper with Wei-Lin. After two years as an academic project, the team incorporated in 2025, and Ion joined as co-founder and executive chairman.
Why We’re Backing Arena
We first met Anastasios in the summer of 2025 and have spent the year since getting to know him and the team. Three things have stood out.
The first is neutrality. Labs compete on Arena’s leaderboards, which only works if no lab owns the scoreboard. That position is hard to earn and easy to lose, and the founders treat it accordingly. They publish their methods, open their data to scrutiny, and respond to criticism with research.
The second is the data, which is unique because the platform is. Unlike other model data providers, Arena doesn’t pay its users. People come to use the models, and the platform draws them organically from a wide range of backgrounds and expertise, which is what a thorough model evaluation needs. Arena has grown that user base to a scale others will struggle to replicate.
The third is the team’s range. Anastasios moves between theoretical statistics, commercial strategy, and the product roadmap without dropping a thread, and Wei-Lin has built and run the platform since its first version. We’ve been consistently impressed by their clear vision and precise execution, especially for such a young company.
We saw firsthand how Anastasios thinks about Arena at Elevate, Salesforce Ventures’ annual CEO Summit, earlier this year. He led a workshop called “Beyond the Leaderboard: Picking the Right Model for Your Product,” walking founders and enterprise leaders through how to read evaluation data against their own use cases instead of chasing whichever model sits at the top. His expertise, ability to distill complex ideas to what matters, and passion for AI evaluation came through clearly, and the session resonated with us and others in the room.
What’s Ahead
Salesforce Ventures is excited to participate in Arena’s Series B alongside Lightspeed Venture Partners, Khosla Ventures, and others. As models take on longer, higher-stakes work, the gap between a benchmark score and real-world behavior gets more expensive to ignore. Arena measures that gap directly, and we’re glad to be backing the team that built the method.
Welcome to Salesforce Ventures, Arena!